- AI / LLM
- Automation
- Internal tool
AI Slack Check
Proposed, built and ran solo a Slack → Vietnamese rules → Claude → PostgreSQL pipeline that replaced HR's manual reading and re-typing of leave, late and remote requests for ~50 employees.
- Role
- Full-stack · built solo
- Team
- Solo
- Timeline
- 03/2026 – 04/2026
- Status
- Retired
~50
Employees covered
18
Automatic runs per workday
~30
REST endpoints
32
Unit tests
 Node.js
 Fastify
 TypeScript
 Claude API
 PostgreSQL
 React
Context
Every morning a Slackbot posts three messages to the company attendance channel: OFF (day off), LATE (late arrival or early leave) and REMOTE (working remotely). Employees reply in each thread in free-form Vietnamese — with @mentions of their mentor, emoji and abbreviations: "Anh @Thuận em xin về sớm lúc 17h15 vì có việc gia đình ạ" ("leaving early at 17:15 for a family matter"), "em đi muộn 15p kẹt xe" ("15 minutes late, traffic jam"), "em off chiều nay và ngày mai" ("off this afternoon and tomorrow").
AI Slack Check is an internal tool I proposed at Protean Studios to turn those messages into structured attendance data for HR.
Problem
HR read every thread by hand each day and re-typed it into the attendance sheet:
- Slow, error-prone and hard to roll up by month.
- Messages have no fixed format: one sentence can request several days, speak for several people, or blur "leaving early" with "taking the afternoon off".
- No number in a report could be traced back to the original message.
My Responsibility
I built it alone end to end: requirements with HR, system design, the Fastify + TypeScript backend, the PostgreSQL database, the LLM prompts, the React dashboard for HR, tests, deployment and running it in production on Vercel, Railway and Supabase.
Constraints
- Free-form Vietnamese with diacritics, abbreviations, emoji and Slack markup.
- A wrong record means a wrong leave balance or payslip, so the LLM could not be trusted blindly and HR had to be able to verify every entry.
- Real data broke assumptions: the bot did not post at 7 a.m. as designed (once at 12:50), and replies kept arriving after a thread had been processed.
- Small budget and infrastructure: Supabase free tier, Vercel Hobby and Railway Starter (~$5/month); Railway's proxy cuts long-running requests.
- Slack display names differ from official names and can change at any time.
Architecture
- The Fastify backend is layered —
SlackService → PreprocessService → LLMService → AttendanceService, orchestrated byDailyCollectorJob— plusRosterService,ReportService,CalendarServiceandAlertService. - Scheduling:
node-cronruns every 30 minutes from 8:00 to 16:30, Monday to Friday (18 runs a day). HR can also trigger a day manually, reprocess a day, or sync a date range. - Database:
bot_messages(threads and sync state),raw_slack_data(original messages),attendance_logs(attendance records),employee_roster,failed_processingandhr_users. - The React frontend (seven pages) is on Vercel;
vercel.jsonrewrites/api/*to the Railway backend, so the browser calls the API on the same origin with no CORS setup.
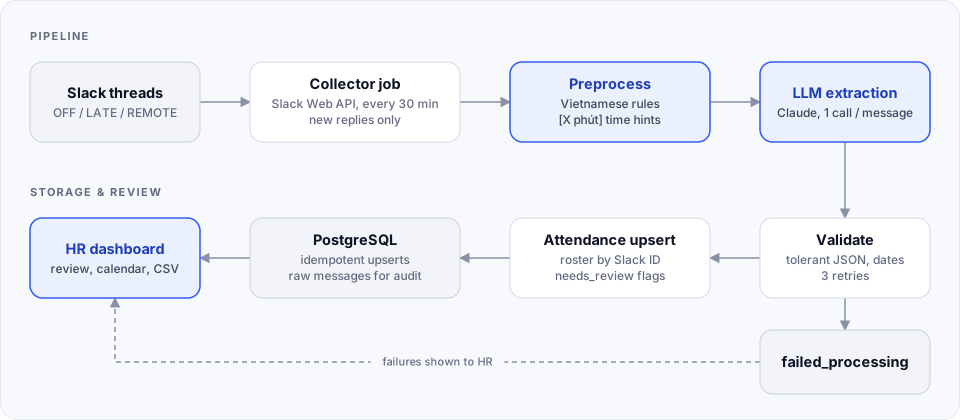
Key Technical Decisions
Rules for what must be exact, the LLM for meaning
- Problem: the LLM miscalculated minutes from "leaving at 17:15", and spent tokens on messages that were not requests at all.
- Decision: Vietnamese preprocessing with rules before any LLM call:
- Strip Slack markup (mentions, URLs, emoji codes and Unicode emoji,
<!here>…). - Filter out non-requests: bot reminders, managers' confirmations, "ok em", "vâng", "thanks".
- Regexes extract early-leave times (
lúc 17h15,về 5 chiều,5pm…) and convert them withminutes early = 18:00 − leave time; "1 tiếng rưỡi" (an hour and a half) becomes 90. - Append a
[X phút]("X minutes") hint to the text sent to the LLM: regexes compute the number, the LLM only classifies.
- Strip Slack markup (mentions, URLs, emoji codes and Unicode emoji,
- Why: arithmetic needs certainty; only intent needs a language model.
- Trade-off: a Vietnamese regex set to maintain (for example
[^\d]*instead of a whitespace class, so it matches accented letters such as "ớ" in "sớm").
One message, one LLM call
- Problem: sending a whole thread in one call made the LLM mix reasons and names between employees.
- Decision: one call per message, with results mapped back to the sender by Slack
ts(unique and stable) and a fallback on accent-stripped names. - Trade-off: more calls, run sequentially, so slower — acceptable for one channel's volume, and the noise filter cuts the number of calls.
A prompt per thread type
- Decision: a short, fixed system prompt (skip rules, date rules, confidence scale, JSON only) and a separate user prompt for OFF, LATE and REMOTE with keywords, an IF → THEN decision tree and few-shot examples with their exact JSON output;
temperature = 0.1. - Hard cases covered: early leave belongs to LATE, not OFF; multi-day leave ("off from the 5th to the 9th" → five records); one message covering several people; a reason only comes from that person's own message.
Treat LLM output as untrusted input
- Decision:
- A tolerant parser that reads JSON inside code fences, plain JSON and truncated JSON (cut back to the last valid
}or]). - Field-by-field validation: confidence clamped to [0, 1], dates normalised (
YYYY-MM-DD,D/M, "today", "tomorrow"), impossible dates (31 April) dropped, duplicates removed by name + date + session, results below 0.2 confidence discarded. - Up to three retries per message when the API fails or the JSON is invalid.
- A tolerant parser that reads JSON inside code fences, plain JSON and truncated JSON (cut back to the last valid
Human in the loop instead of full automation
- Decision: records are flagged
needs_reviewwith a reason when confidence is below 0.8, a LATE record has no minutes, or the employee is not in the roster. Every record on the dashboard opens a panel with that person's original Slack message; HR clears flags one by one or per day and can mark a message invalid. Thread failures, and cases where "the LLM returned nothing although there were valid messages", go tofailed_processingwith a likely cause. - Why: HR owns the final attendance data; the system's job is to surface exactly the records worth checking.
Incremental sync and idempotent writes
- Problem: late replies were missed, and reruns must not create duplicates or call the LLM again.
- Decision: threads are recognised by content, not posting time, within a 06:50–23:59 window; every run re-reads all threads and compares
reply_tswithlast_reply_tsto process only new replies;attendance_logsis upserted on(employee_slack_id, date, type, duration)withRETURNING (xmax = 0)to count inserts versus updates. Because the key includesduration, one person can be OFF in the afternoon and REMOTE in the morning of the same day.
Identity by Slack ID, not by name
- Decision:
employee_rosteris keyed byslack_id; channel members are synced from Slack (cursor pagination, bots and deleted accounts excluded), HR assigns official names one by one or in bulk, and Vietnamese names are normalised (Unicode NFD, accents stripped, lowercase). Once assigned, mapping employees never depends on the LLM's judgement.
SSE for long jobs behind a proxy
- Problem: syncing 31 days was cut off by Railway's proxy timeout.
- Decision: process three days in parallel (
Promise.allSettled, so one failed day does not sink the batch) and stream progress with Server-Sent Events (X-Accel-Buffering: no). The frontend reads the stream withfetch+ReadableStream, becauseEventSourcecannot send a POST with a JWT header.
Trade-offs
- Sequential LLM calls per message: correct and easy to debug, but slower; the way forward is bounded parallelism, prompt caching or a batch API.
- node-cron inside the process: simple for a single instance, not suited to horizontal scaling.
- Plain SQL with
pg, no ORM: full control of queries (COUNT(*) FILTER, upserts, partial indexes), at the cost of writing my own migration runner. - An
LLMProviderinterface (Anthropic SDK or an OpenAI-compatible endpoint) switchable by environment variable — a small abstraction that let me test against a cheaper proxy without code changes. - Some values are still fixed (18:00 end of day) — fine for one company, configurable if it were used more widely.
Implementation Highlights
- Slack: three retries with 1–30 s exponential backoff and jitter; the bot joins channels itself; user profiles cached in memory (5-minute TTL); @mentions parsed in both
<@U123|Name>and<@U123>forms and stored as the request's mentors; a fix for parent messages being skipped, usingthread_ts !== ts— found while testing with real data. - Performance: the roster loads once per run into a
Map(O(1) lookups) instead of one query per record. - Reports for HR: monthly roll-ups with
COUNT(*) FILTER (WHERE …); a calendar-style attendance matrix (employees × days, each cell showing OFF / LATE / REMOTE at once); most-late rankings and 7-day trends; CSV export by any filter. Every filter uses parameterised queries. - Seven-page dashboard: KPIs, Recharts charts, daily detail with the original messages, monthly roll-ups, the attendance matrix, employee management synced from Slack, and failures; a shared
FilterBarwith debounce; a typed API client. - Database: a custom migration runner; the schema evolved over eight migrations — a partial index
WHERE needs_review = TRUE, removing duplicates before adding a unique constraint, and moving from the oldemployeestable toemployee_roster. - Operations: multi-stage Docker builds; a three-service Docker Compose setup for local work (Postgres with a health check that runs migrations on start); DB and Slack checks at startup,
/api/health, graceful shutdown, structured logs with pino; continuous deployment from GitHub across eight pull requests. - Tests: 32 unit tests (19 for preprocessing, 13 for timezone handling) with fixtures from real Slack messages.
Result / Impact
- Ran in production on Vercel, Railway and Supabase for about $5 a month in infrastructure.
- HR no longer read and re-typed every thread; monthly reports per employee exported in one click.
- Every attendance record traced back to its original Slack message, and suspicious records surfaced for review automatically.
- The tool was retired in May 2026.
What I Learned
- Run on real data as early as possible: the bot's posting time, the parent/child thread structure and late replies all differed from the initial assumptions.
- Give the parts that must be exact (minutes, dates) to rules and the parts that need understanding to the LLM — more accurate and cheaper.
- Treat LLM output like user input: parse defensively, validate, normalise, and always keep the source data for comparison.
- Idempotency and the ability to reprocess (rerun a day, backfill a range) have to exist from day one in any scheduled pipeline.